62.7 and 99.9: same model, same exam, two scores
OpenAI published 99.9% on ARC-AGI-3 for GPT-6 Astra. ARC Prize measured 62.7% the same day. The difference is the harness, and it explains why benchmark tables no longer compare models.
OpenAI published 99.9% on ARC-AGI-3 for GPT-6 Astra. ARC Prize measured 62.7% the same day. The difference is the harness, and it explains why benchmark tables no longer compare models.
Claude Code writes the orchestration script, launches a fleet of subagents, and the coordination doesn’t cost a single token. Third installment: from the loop to a graph that runs itself.
Google published a 51-page whitepaper on the new software lifecycle with vibe coding. The conceptual framework — the spectrum, Agent = Model + Harness, the factory model — is excellent. The statistical apparatus collapses at the first question. A layer-by-layer review, with all nine headline figures traced to their primary sources.
Graphify turns a repository into a deterministic knowledge graph with no embeddings and no LLM cost. Its benchmark is one of the best in the sector — and it contains the row that dismantles its own headline: four thousandths over a classic hybrid RRF. A technical read of the pipeline, the numbers and the defaults.
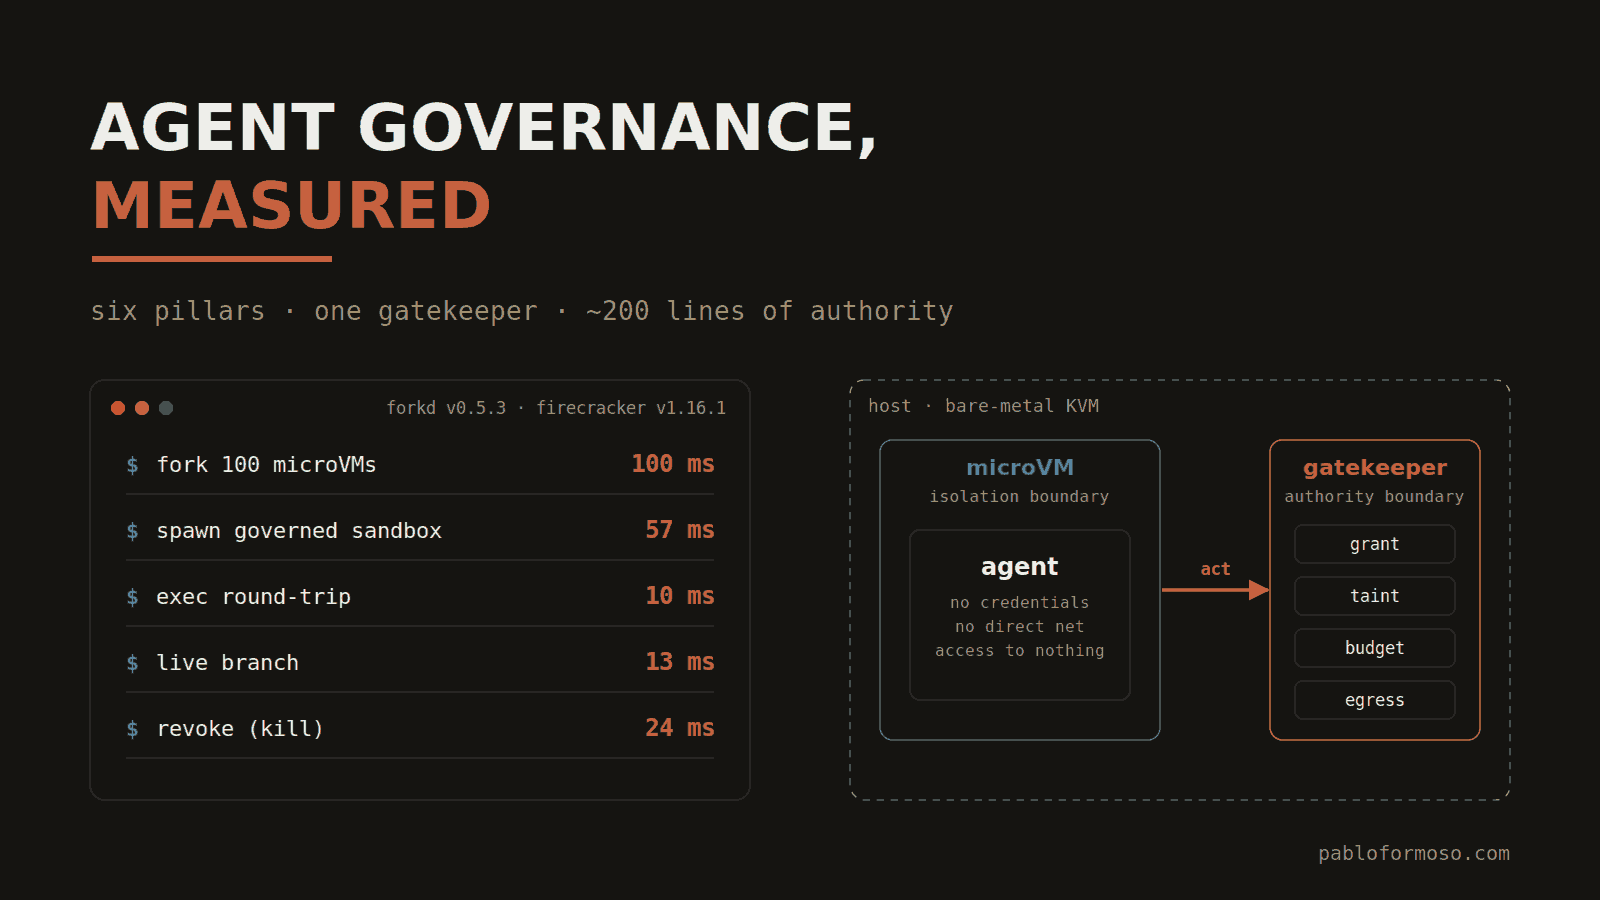
Agent governance is usually discussed as doctrine. We took it to a test bench: a ~200-line gatekeeper, warm-forked microVMs, and four models unknowingly trying to break the rules. The numbers, the prompt-injection matrix, and the two leaks that taught us the most.
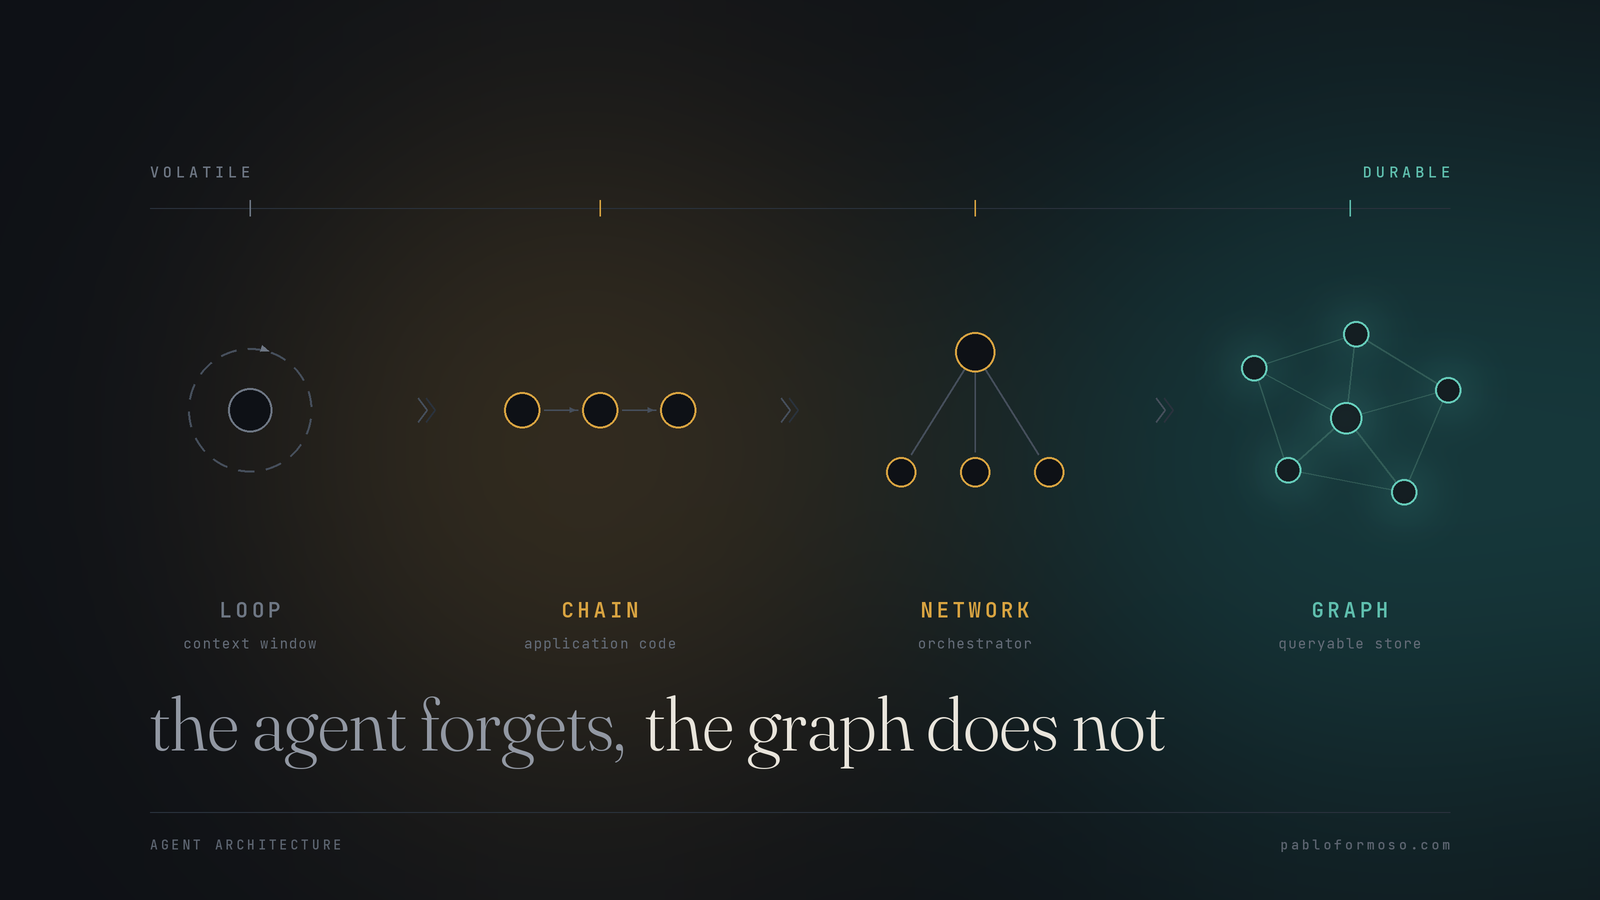
Ng’s four patterns are still the right vocabulary, but the real axis in agent architecture isn’t how many agents you have — it’s where the state lives. An honest walk from loops to graphs, and what has changed since 2024.
Loop engineering without the smoke: the anatomy of an autonomous loop, how I run mine with a GitHub board and subagents, and the Claude Code parts that make it possible.