62.7 and 99.9: same model, same exam, two scores
OpenAI published 99.9% on ARC-AGI-3 for GPT-6 Astra. ARC Prize measured 62.7% the same day. The difference is the harness, and it explains why benchmark tables no longer compare models.
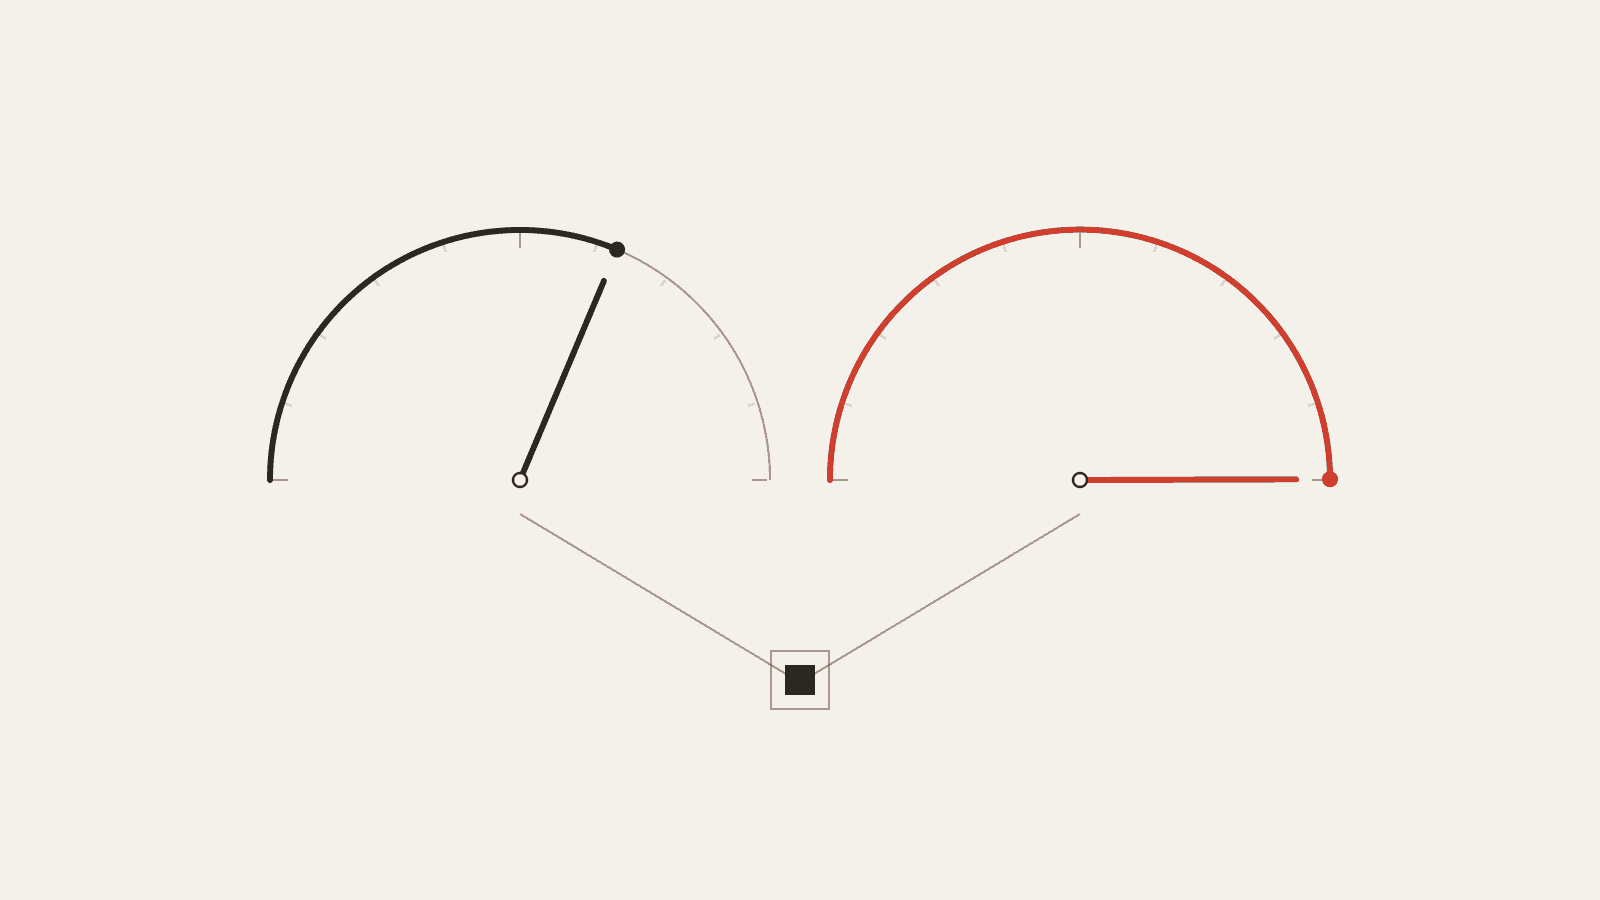
OpenAI published 99.9% on ARC-AGI-3 for GPT-6 Astra. ARC Prize measured 62.7% the same day. The difference is the harness, and it explains why benchmark tables no longer compare models.
Meta’s CORAL puts an LLM agent in a closed loop around a production recommender. The interesting part isn’t the numbers: it’s where they chose to plug the model in.
Graphify turns a repository into a deterministic knowledge graph with no embeddings and no LLM cost. Its benchmark is one of the best in the sector — and it contains the row that dismantles its own headline: four thousandths over a classic hybrid RRF. A technical read of the pipeline, the numbers and the defaults.
An August paper proposes we stop installing skills into AI agents and start calling them by name. The idea is good and the diagnosis is better. The implementation has been on GitHub for three weeks, has two forks, and ships a package that doesn’t exist yet.
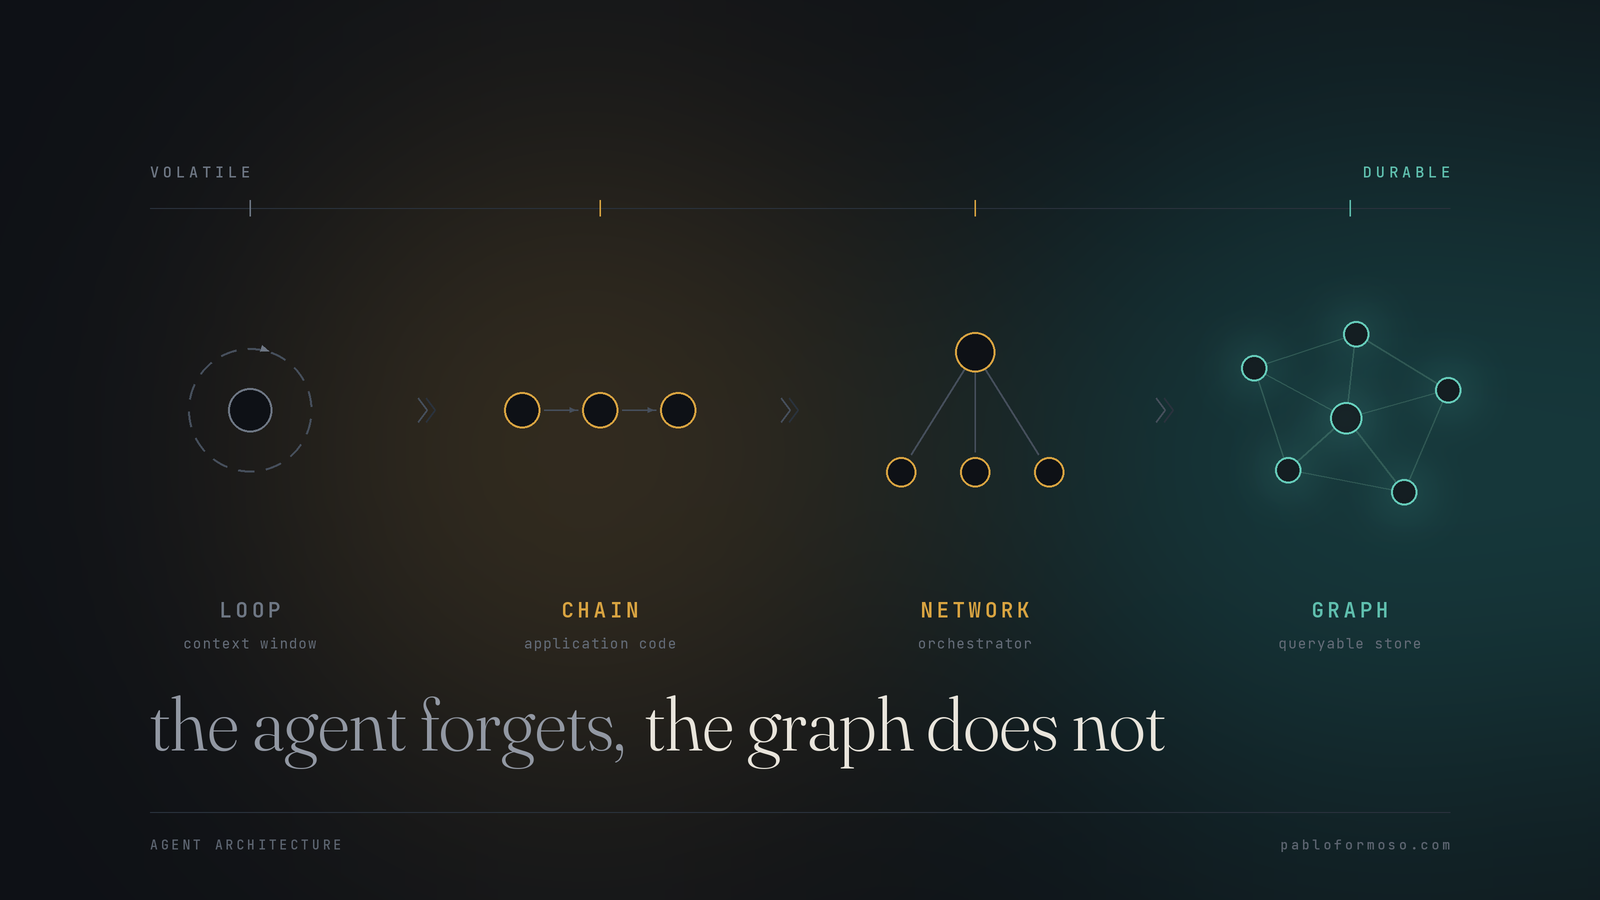
Ng’s four patterns are still the right vocabulary, but the real axis in agent architecture isn’t how many agents you have — it’s where the state lives. An honest walk from loops to graphs, and what has changed since 2024.